
Data Scientist, ML and GenAI Interview Preparation: Questions and Model Answers
A compact question bank with model answers for data scientist, ML engineer and GenAI roles: Python and pandas, statistics, ML fundamentals, model evaluation, feature engineering, system and case design (churn, fraud, recommendations), MLOps, LLMs, RAG and agents, plus how to handle take-home assignments and live coding.
- Answer core Python, statistics and ML questions concisely
- Walk through an end-to-end ML system design
- Explain LLM, RAG and agent concepts and trade-offs
- Plan and present take-home assignments
Python and pandas (quick answers)
| Question | Answer |
|---|---|
| List vs tuple vs set vs dict? | Mutable sequence / immutable record / unique unordered / key→value; sets and dicts give O(1) lookups |
apply vs vectorisation? |
Vectorised column operations run in C and are much faster; avoid apply(axis=1) on large data |
merge vs join vs concat? |
merge on columns, join on index, concat stacks |
| How to handle missing values? | Understand why, then drop, impute (median, group-wise, model) or flag; impute inside CV |
| Generator vs list? | Generators are lazy and memory-efficient, consumed once |
Statistics and ML fundamentals
| Question | Model answer |
|---|---|
| Bias-variance trade-off? | Simple models underfit (bias), complex models overfit (variance); choose complexity by validation error |
| L1 vs L2? | L1 zeroes coefficients (selection); L2 shrinks smoothly; Elastic Net mixes |
| Why cross-validation? | A single split is noisy; k-fold averages and supports tuning without touching the test set |
| Precision vs recall? | Precision: flagged that are right; recall: positives caught; choose by error costs |
| ROC-AUC vs PR-AUC? | PR-AUC is more informative for rare positives |
| Bagging vs boosting? | Parallel averaging (variance) vs sequential error correction (bias) |
| How does gradient descent work? | Iteratively step weights against the loss gradient with a learning rate |
| What is data leakage? | Using information unavailable at prediction time; prevent with pipelines, time-based splits and feature cut-offs |
| p-value? | Probability of data at least this extreme if H0 were true; not the probability H0 is true |
ML system design: a template
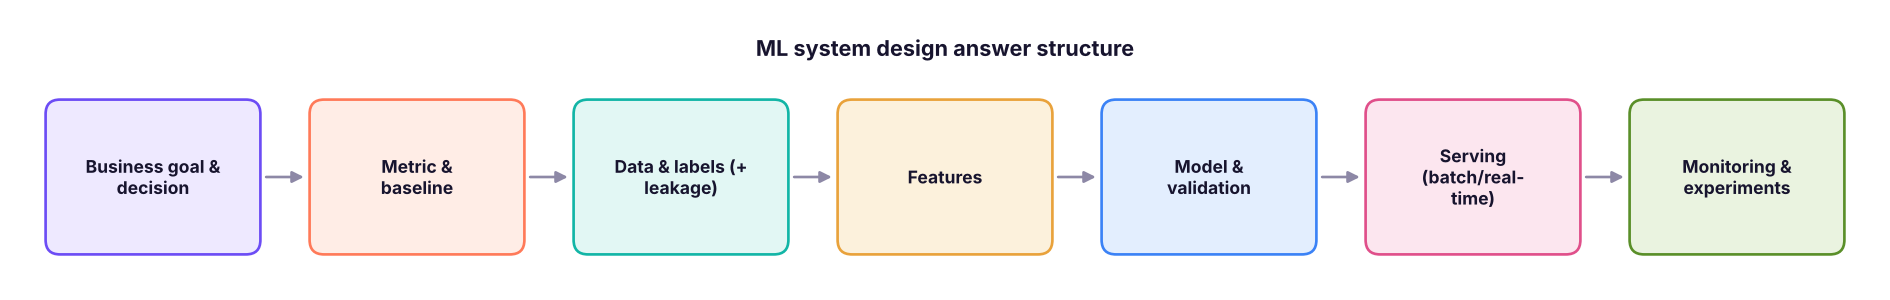
Example: "Design a fraud detection system for UPI payments." Real-time decision under 100 ms; label = confirmed fraud (delayed, imbalanced); features: amount vs user history, device/location change, merchant risk, velocity, graph links; model: gradient boosting + rules + anomaly scores; evaluate PR-AUC and recall at alert capacity; serve with a feature store and low-latency API; monitor drift and attack patterns; human review queue; A/B test thresholds.
LLM, RAG and agent questions
| Question | Model answer |
|---|---|
| How do LLMs work? | Transformers trained to predict the next token, then instruction-tuned and aligned with feedback |
| RAG vs fine-tuning? | RAG for changing knowledge with citations; fine-tuning for behaviour/format |
| How to evaluate a RAG system? | Retrieval hit rate/MRR + answer correctness, faithfulness, abstention on a labelled set |
| How to reduce hallucinations? | Grounding, tools, "say I don't know", citations, validation, evaluation |
| What is an agent? | An LLM in a loop choosing tool actions toward a goal, with memory and stopping conditions |
| What is MCP? | Open protocol to connect assistants to tools/data via servers (tools, resources, prompts) |
| Prompt injection defence? | Separate data from instructions, least-privilege tools, approvals, output checks |
| Cost control? | Model routing, caching, batching, shorter context and outputs |
Take-home assignments
- Restate the problem and assumptions in the first lines of your report.
- Do a focused EDA; do not chart everything.
- Baseline first, then 1–2 better models; validate correctly.
- Translate results into business impact and a recommendation.
- Clean, runnable code (requirements, README); a 5-slide summary.
- State limitations and next steps honestly.
Live coding tips
Clarify inputs/outputs and edge cases, start with a simple correct solution, test with a small example, then optimise and state Big-O (Python DSA lessons 26–28).
- Answer concisely, then go deeper only if asked.
- Use the design template: goal → metric → data → features → model → serving → monitoring.
- Know LLM/RAG/agent trade-offs, evaluation and safety.
- Take-homes: baseline, correct validation, business recommendation, clean code, honest limitations.
1. What should you state first in an ML system-design answer?
2. Best metric for a fraud model with 0.5% fraud?
3. RAG or fine-tuning for policy documents that change monthly?
4. What must a take-home report include besides the model?
(1) Answer "Design a product recommendation system for an e-commerce home page" using the template. (2) Explain RAG to a non-technical manager in 60 seconds. (3) Do one timed take-home on the telecom churn data (3 hours).
Show solution
Recommendations: goal = revenue per session; candidates via collaborative filtering/embeddings + popularity; ranking model with user, item and context features; offline metrics (recall@k, NDCG) + online A/B test on revenue; cold start with popular/contextual items; monitor diversity and drift.
Practise more online
Free, trusted places to test yourself on this topic. Links open the original site in a new tab.